Data Science on the Google Cloud Platform, 1st Edition
Reading Journey
Started: 2022-02-24T15:48:40Z
Ended: 2022-02-28T14:42:20Z
Total Time Read: 5hrs 11mins 30secs
Code
%run _help_reading.pyimport pandas as pddf = pd.read_csv('https://github.com/MrGeislinger/victorsothervector/raw/main/''data/reading/all_reading-clean.csv')book_name ="""Data Science on the Google Cloud Platform, 1st Edition"""one_title = one_title_data(df, book_name)one_title_summary = get_summary_by_day(one_title)generate_plot(one_title_summary, book_name);
/Users/victor/Developer/Workspace/victorsothervector/books/_help_reading.py:78: UserWarning: set_ticklabels() should only be used with a fixed number of ticks, i.e. after set_ticks() or using a FixedLocator. Otherwise, ticks may be mislabeled.
  ax.set_xticklabels(
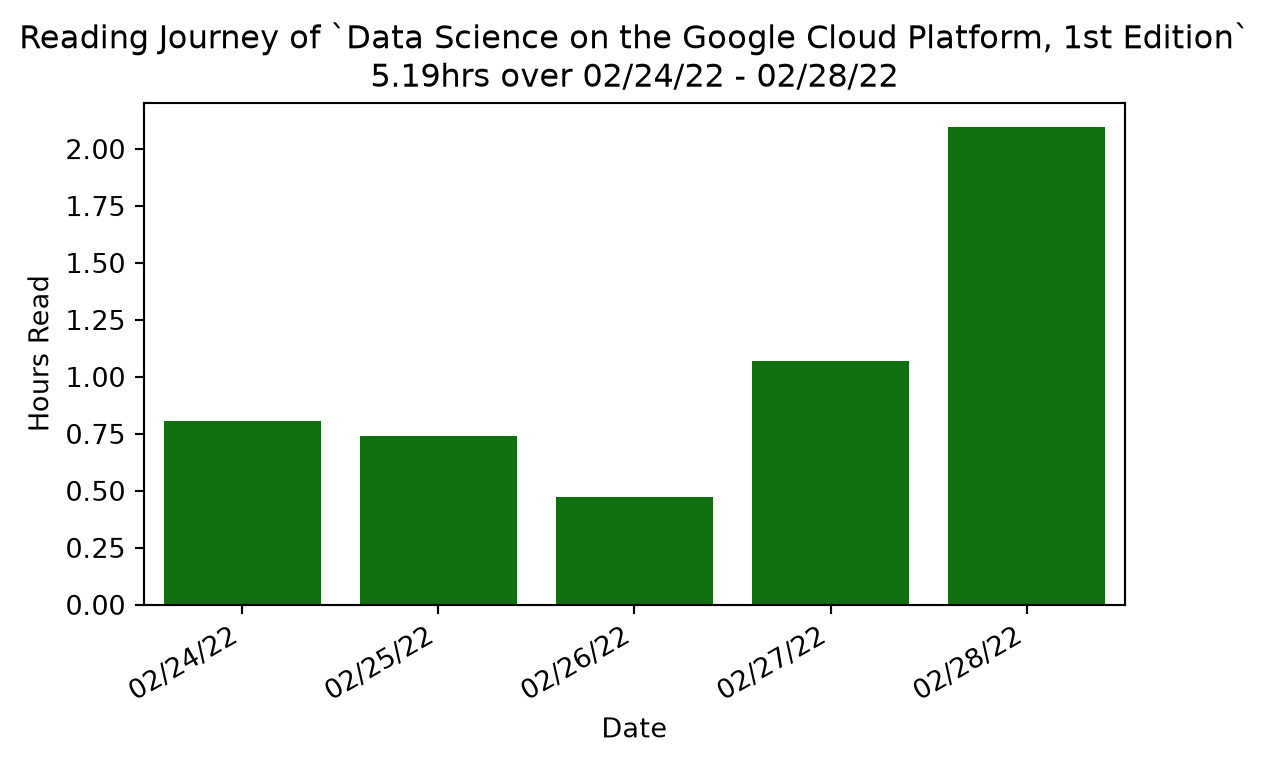
Figure 1: Reading done for Data Science on the Google Cloud Platform, 1st Edition
title: “Data Science on the Google Cloud Platform, 1st Edition” book: title: “Data Science on the Google Cloud Platform, 1st Edition” format: html: code-fold: true creator: “@victorgeislinger” —
Thoughts on Data Science on the Google Cloud Platform, 1st Edition
Overview
Learn how easy it is to apply sophisticated statistical and machine learning methods to real-world problems when you build using Google Cloud Platform (GCP). This hands-on guide shows data engineers and data scientists how to implement an end-to-end data pipeline with cloud native tools on GCP. Throughout this updated second edition, you’ll work through a sample business decision by employing a variety of data science approaches. Follow along by building a data pipeline in your own project on GCP, and discover how to solve data science problems in a transformative and more collaborative way. You’ll learn how to: Employ best practices in building highly scalable data and ML pipelines on Google Cloud Automate and schedule data ingest using Cloud Run Create and populate a dashboard in Data Studio Build a real-time analytics pipeline using Pub/Sub, Dataflow, and BigQuery Conduct interactive data exploration with BigQuery Create a Bayesian model with Spark on Cloud Dataproc Forecast time series and do anomaly detection with BigQuery ML Aggregate within time windows with Dataflow Train explainable machine learning models with Vertex AI Operationalize ML with Vertex AI Pipelines